Kafka From Zero to Hero: Zero-Downtime Kafka Migration
Originally published on Medium (May 2019). Photo in the banner by Nghia Le on Unsplash.
Intro
Half a year ago, I started working at Blockport — a cryptocurrency exchange trying to combine trading with social networking, where experienced traders can share their knowledge with newcomers and get rewarded for it in BPT (Blockport token).
I’d always wanted to work at a startup. Being an expat in the Netherlands, I have some limitations on which companies I can work for, and at the same time I’m fairly picky about the technology a product is built on. Blockport turned out to be the right fit — they’d successfully run an ICO, so had the funding to hire expats, and their applications ran on Kubernetes on Google Cloud, exactly what I was after.
At a startup, there’s always more that needs doing than time to do it properly, and that comes with compromises — shipping something fast rather than with the best long-term design.
One of those decisions was the Kafka deployment. Kafka is our microservices’ message bus, giving us delivery guarantees: if a service goes down, its messages stay in Kafka for another instance to pick up later. To ship a Kafka cluster quickly, the first attempt ran it on Kubernetes, even though stateful workloads are generally considered a hard problem there. I wasn’t at Blockport yet at that point, so I can’t speak to the details, but it wasn’t stable enough — the cluster moved to virtual machines on Google Compute Engine after that.
Still trying to avoid a deep fight with Kafka’s internals, the cluster was then deployed using a managed solution from the Google Cloud Marketplace. Eventually, we rebuilt the whole setup from scratch — this is the story of why, and the path we took.
Kafka topics
Using a pre-configured Kafka felt fine at first, even though a teammate had to patch it to run securely, entirely on our private network at Google.
We’re a 2.5-person DevOps/SRE team (our CTO pitches in on security and automation from time to time), and keeping our infrastructure available and secure is the job — Kafka is a vital piece of that.
To check on high availability, we started running disaster-recovery tests against our staging cluster. During one of them, developers reported lost messages. Investigating, we found auto.create.topics.enable=true on the cluster, which lets messages get posted to a topic that doesn’t exist yet — auto-created that way, every topic got a single replica per partition, a consequence of using a pre-configured, not-fully-vetted solution (auto-topic-creation was on for developer convenience; the single-replica default came along for the ride, unnoticed).
On top of that, some topics were pre-created by the microservices themselves, often with just one replica, even though we had five Kafka brokers available. That’s a real red flag — any single broker failure could lose messages. So the first, obvious fix was raising the replica count across every topic and agreeing on sane availability settings going forward.
Kafka high availability settings
Here’s what we settled on:
# When a producer sets acks to "all" (or "-1"), min.insync.replicas specifies the minimum number of replicas
# that must acknowledge a write for the write to be considered successful. If this minimum cannot be met,
# then the producer will raise an exception (either NotEnoughReplicas or NotEnoughReplicasAfterAppend).
# When used together, min.insync.replicas and acks allow you to enforce greater durability guarantees.
# A typical scenario would be to create a topic with a replication factor of 3, set min.insync.replicas to 2,
# and produce with acks of "all". This will ensure that the producer raises an exception if a majority of replicas
# do not receive a write.
min.insync.replicas=2

# Default replication factors for automatically created topics
default.replication.factor=4

############################# Internal Topic Settings #############################
# The replication factor for the group metadata internal topics "__consumer_offsets" and "__transaction_state"
# For anything other than development testing, a value greater than 1 is recommended for to ensure availability such as 3.
offsets.topic.replication.factor=4
transaction.state.log.replication.factor=4
transaction.state.log.min.isr=2
You might wonder why we set the replica count to four when the official docs suggest three. A five-node Kafka cluster can survive two node failures. When we tested with a three-replica topic and shut down a single server, we still had two replicas available and applications could keep reading and writing (Kafka doesn’t automatically move dead replicas to other available servers). Reads and writes still worked with one server down, thanks to min.insync.replicas=2. But after shutting down a second server, even though we still had one replica left — no data loss — applications could no longer write to the topic, since only one synchronized replica remained out of the two required. Four replicas gives us the maximum tolerable failures while keeping topics writable and readable.
You might also ask how likely it is that two servers actually go down together. It happened to us not long after. One of the best practices in a distributed setup is spreading servers across multiple zones or data centers — Google Cloud has three zones, so we ran two Kafka brokers in zone A, two in zone B, and one in zone C. Zone A had an outage, which meant our cluster hit the worst case it could currently handle: two brokers partitioned away from the rest. Good thing we were prepared.
One more setting relevant to multi-datacenter setups: rack awareness. We could have used it, but with four replicas it wouldn’t have bought us anything more. The worst-case distribution of four replicas across five servers in three zones puts two replicas in zone A and two in zone B (a single server can’t hold multiple replicas of the same partition). If a whole zone goes down, as it did, we’re still fine with the two replicas in the other zone. But if even one more server goes down after that, we’re in trouble regardless of whether the last two replicas were in one zone or split across two.
Beyond the server-side replica settings, we asked every developer to set acks=all in their Kafka producer config, so enough replicas get updated on every write and we don’t lose messages if a broker or producer fails mid-write. retries=3 is another good producer setting, to ride out intermittent network issues — though most Kafka client libraries already default to something like it.
Fixing the replication factor
Kafka lets you raise or lower a topic’s replica count following this approach. That works fine — until you need to do it for over a hundred topics by hand. So I wrote a script that does it for every topic on a cluster. It’s not the finest bash scripting, but it does the job, and it has a check mode useful for finding under-replicated topics on its own. There’s a native Kafka command,
kafka-topics.sh --zookeeper zookeeper:2181 --describe --under-replicated-partitionsbut it only shows partitions with an active replication problem, while this script compares the current replication factor against the desired one directly:
#!/bin/bash
CHECK_MODE=true
REPLICAS=4
ZK="zookeeper.local:2181"
TEMPLATE='topic_update.json'
TOPICS=$(kafka-topics.sh --zookeeper $ZK --list )
BROKERS=(0 1 2 3 4)

# If you have zkCli on your Kafka server, you can get broker IDs dynamically like this
# broker_ids=($(zkCli.sh -server $ZK ls /brokers/ids | tail -1 | tr -d '[],'))

# Params:
# 1. template_file
generate_template() {
  cat <<EOF > $1
{
  "version": 1,
  "partitions": [
  ]
}
EOF
}

get_new_replicas() {
  random_brokers=($(printf '%s\n' "${BROKERS[@]}" | shuf)) # shuffle broker list to balance replicas across all brokers
  replica_list=(${random_brokers[@]::$REPLICAS}) # retrieve only the required number of replicas from the broker list
  printf '%s\n' "$(IFS=,; echo "${replica_list[*]}")" # coma-separated replica list
}

# Params:
# 1. template_file
# 2. topic_name
# 3. partition_count
populate_template() {
  last_part_id=$(expr $3 - 1)
  for P in $(seq 0 $last_part_id); do
    replicas=$(get_new_replicas)
    if [ "$P" -eq 0 ]; then
      sed -i "/partitions/a {\"topic\": \"$2\", \"partition\": $P, \"replicas\": [$replicas]}" $1
    else
      sed -i "/partitions/a {\"topic\": \"$2\", \"partition\": $P, \"replicas\": [$replicas]}," $1
    fi
  done
}

# Params:
# 1. zookeeper_address
# 2. template_file
verify_replication() {
  while true; do
    result=$(kafka-reassign-partitions.sh --zookeeper $1 --reassignment-json-file $2 --verify | grep "is still in progress")
    if [ -z "$result" ]; then
      echo "reassingment succeeded"
      break
    fi
  done
}

rebalance_topics() {
  updated_topics=0
  for T in $TOPICS; do
    echo "Checking topic $T"
    topic_params=$(kafka-topics.sh --zookeeper $ZK --describe --topic $T | egrep "ReplicationFactor")
    topic_replicas=$(echo $topic_params | cut -d ':' -f 4 | head -c1)
    topic_partitions=$(echo $topic_params | cut -d ' ' -f 2 | cut -d ':' -f 2)
    if [ "$CHECK_MODE" = false ]; then
      echo "Starting replication of underreplicated partitions in topic $T"
      generate_template $TEMPLATE
      populate_template $TEMPLATE $T $topic_partitions
      kafka-reassign-partitions.sh --zookeeper $ZK --reassignment-json-file $TEMPLATE --execute
      verify_replication $ZK $TEMPLATE
      let updated_topics+=1
    elif [ "$topic_replicas" = "$REPLICAS" ]; then
      echo -e "Topic $T already has $REPLICAS replicas on all partitions\n"
      continue
    else
      echo -e "Topic $T has $topic_replicas replicas versus $REPLICAS requested, partition reassingment needed\n"
    fi
  done
  echo "$updated_topics topics were updated to have $REPLICAS replicas on all partitions on $STAGE kafka"
}

rebalance_topics
If you don’t feel like reading the code (or my code is just bad): the script generates the JSON files needed to change a topic’s replication factor, with a randomized broker list so the load spreads evenly across the cluster rather than making one broker the leader for every partition. That distribution matters — all reads and writes go to a partition’s leader, never its replicas, so a single machine holding every leadership role would get overloaded fast. Once the JSON is generated, the script kicks off partition reassignment and waits for it to finish, which can take a while depending on message volume and cluster performance.
The official Kafka docs describe exactly the problem this script solves:
An ideal partition distribution would ensure even data load and partition sizes across all brokers. The partition reassignment tool does not have the capability to automatically study the data distribution in a Kafka cluster and move partitions around to attain an even load distribution. As such, the admin has to figure out which topics or partitions should be moved around.
With the script in hand, we started raising the replication factor across every topic. Testing on a fresh cluster and staging went smoothly; our pre-live cluster hit issues that took hours to debug. I got pre-live back to a healthy state, but never nailed down the root cause — a red flag that running the same procedure against the live cluster might not go so cleanly. A Kafka expert might have spotted the cause immediately, but most engineers I talked to had had similarly rough debugging experiences with Kafka clusters. Around the same time, developers were also reporting Kafka bugs unrelated to replication. We were running Kafka 1.1, with 2.1.0 already out, so it seemed worth upgrading before fighting problems that a newer version might have already fixed — including, maybe, our replication issues.
Kafka setup from scratch
With an upgrade already on the table, we looked harder at the pre-configured setup itself. It provided reasonable defaults, but turned out to be painful to change or upgrade. Every server ran under a specific systemd service that was really just an umbrella for whatever the marketplace solution’s underlying applications were — meaning you couldn’t easily find “the Kafka service” by logging into the machine. After some digging, we found the actual Kafka process was managed by gonit, and more than once I ran into that umbrella service reporting healthy while Kafka itself was down — a real drawback of stacking several layers of service management on top of each other. Another problem: the setup used Google Deployment Manager, which — unlike Terraform — doesn’t reconcile state if a VM gets deleted outside of it. Any change to the cluster’s size risked painful manual edits to Jinja or YAML files pulled from the Deployment Manager console. We also ran into breaking changes across Google API versions during our short time using it — the older API version (from our initial marketplace deployment) required network and subnetwork fields on a static IP resource:
- name: {{ name }}-static-ip
  type: compute.v1.address
  properties:
    addressType: INTERNAL
    {# network: {{ path_utils.networkPath(network) }} #}
    subnetwork: {{ path_utils.subnetworkPath(zone, subnetwork) }}
    region: {{ region }}
while the newer API refused to create the resource unless you commented out one field or the other. Reconciling two versions of the same Jinja template while already fighting a pre-live cluster issue was not a fun afternoon. All told, we decided a from-scratch Kafka cluster built with Terraform and Ansible would give us everything we actually needed going forward — proper integration with Google’s APIs, including real state management, and full control over Kafka’s processes and configuration on the VMs themselves.
The original setup wasn’t wasted, though — it was a useful reference while writing our own automation. For instance, we set up Kafka’s data disks separately from boot disks, matching the official docs’ recommendation (something we only really understood once we saw it done). Our Terraform is fairly standard, but the startup script that mounts the attached data disk and applies the disk performance settings Kafka’s admin guide recommends seemed worth sharing:
#!/bin/bash
KAFKA_DIR=/mnt/disks/kafka-data
DISK=/dev/sdb

# check/create filesystem on attached disk
filesystem=$(lsblk "$DISK" -f | grep ext4)
if [ -z "$filesystem" ]; then
  mkfs.ext4 -m 0 -F -E lazy_itable_init=0,lazy_journal_init=0,discard "$DISK"
fi

mkdir -p $KAFKA_DIR

# check/mount disk to kafka folder
block_id=$(blkid -s UUID -o value "$DISK")
kafka_mount=$(grep kafka /etc/fstab) # check if there is entry in fstab for kafka mount point
if [ -z "$kafka_mount" ]; then
  echo UUID=$block_id $KAFKA_DIR ext4 discard,defaults,nofail,noatime,data=writeback,delalloc 0 2 | tee -a /etc/fstab # http://kafka.apache.org/documentation.html#generalfs
fi
mount -a
A couple of other things worth sharing about the setup: we added node exporter, kafka exporter, and jmx exporter to get real Kafka metrics into Prometheus, and the Google Stackdriver agent to keep different Kafka logs separated for easier debugging:
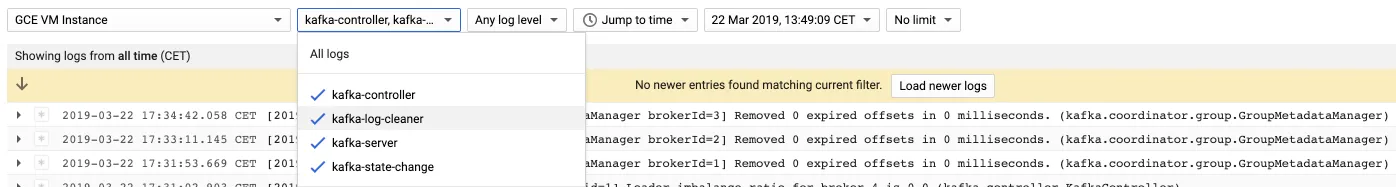
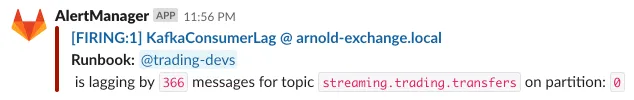
and those Prometheus metrics let us set up genuinely useful alerts for when Kafka goes down, or an app falls behind on a topic:
Kafka migration
With the new scripts ready, the plan was simple: start the new clusters, point DNS at the new machines, maybe restart the Kubernetes pods if they didn’t pick up the address change on their own, and call it done. That seemed reasonable — before automating the new clusters, we’d discussed the new setup with developers, and since Kafka held no business-critical data, we were aiming for a straightforward lift and shift. But, as it usually goes, that early discussion stayed high-level and didn’t cover every use case — it turned out we couldn’t migrate without preserving data after all. The data at risk wasn’t business-critical (no trades or anything like that would be lost), but losing it would break the user experience for a day or two: we needed historical currency prices for little UI badges showing price changes, a feature that probably didn’t exist yet when the original automation work started. Circumstances changed again, so we needed a way to actually preserve the data.
A quick note on DNS: Kafka brokers have to be reachable directly by clients and producers, since reads and writes go straight to a partition’s leader. So while the cluster has a single DNS address, that address is only ever used for discovery. A client sends a metadata request to find out where to read (or write) data, then talks directly to that specific server. Since the metadata request can hit any broker, applications never need to maintain their own broker list — they discover brokers via DNS. If a metadata request happens to hit a dead server, that’s exactly where retries=3 earns its keep. Once a metadata request succeeds, the cluster DNS address is out of the picture entirely.
Integration points
The standard procedure for adding a node to a Kafka cluster is to start the new server and point it at the Zookeeper cluster (Zookeeper tracks partition leaders and available brokers, among other cluster state). Given our original setup already had solid security defaults, that meant new servers needed the same authentication credentials as the old ones — in practice, some manual copying of Kafka credentials into the Ansible scripts provisioning the new servers, since without them we couldn’t join the existing cluster at all.
On the Zookeeper node, check zoo_jaas.conf and copy the value for user_kafka:
Server {
  org.apache.zookeeper.server.auth.DigestLoginModule required
  user_kafka="e038eca2674a94c883d9242970ee9ca5c7"
  user_zkcli="1d58e0c657b6cc0cb604b63a19880b4440ce35";
};
Then use that value for the new Kafka servers, in kafka_jaas.conf:
Client {
  org.apache.kafka.common.security.plain.PlainLoginModule required
  username="kafka"
  password="e038eca2674a94c883d9242970ee9ca5c7";
};
The second thing to think through: the original plan was to restart apps pointing at a new, 2.1.0 cluster and be done. With the data-preservation requirement now in play, we instead had to join new-version nodes to the old-version cluster. Kafka allows exactly that, via inter.broker.protocol.version, documented here — not a big deal on its own, but every extra step adds complexity to the overall process.
Another critical detail: new servers’ broker IDs can’t overlap with the old ones. We disabled automatic broker ID generation (which the managed cluster had used) and assigned static IDs from 0 to 4 by hand.
Finally, we’d already written automation for Zookeeper — but couldn’t reuse it here, since we were staying on the existing Zookeeper cluster (it was already on the latest version, so there was no pressing need to touch it, and migrating Zookeeper is a whole separate story we chose to skip for now). That earlier automation work wasn’t entirely wasted, though — without having done it, we wouldn’t have already known where the Kafka and Zookeeper authentication details lived, which turned out to matter quite a bit here.
Migration plan
Weighing all of that, here’s the plan we settled on for getting data onto the new clusters:
- Add new Kafka servers (2.1.0) to the old cluster, using
inter.broker.protocol.version=1.1and the existing Zookeeper authentication credentials. - Add the new servers to DNS, so every Kafka client can reach them even before they hold any data.
- Start copying data to the new servers by running the replication script above, non-intrusively: every topic stays available for reads and writes throughout, because the broker list always keeps two old servers in it, preserving the minimum synchronized replicas and limiting how much data moves at once (data movement can also be throttled directly, via Kafka’s throttling feature).
- Stop the old servers, remove them from DNS, and leave the cluster running for a few days of testing before going further.
- Restart the Kafka servers one at a time with
inter.broker.protocol.version=2.1, watching the logs closely. If the first two go well, continue with the rest; if not, roll back — still possible at this point, since most servers are still on the old protocol. The protocol change itself is irreversible once applied everywhere, so rolling back past that point would mean deleting machines and reprovisioning them from scratch with Terraform and Ansible.
Migration process
With everything ready, we tested the procedure on staging and pre-live first. With five new nodes (IDs 0–4) and five old ones (IDs 1001–1005), the data migration went in three steps:
- Migrate every topic onto servers
[0, 1005, 1004, 1003, 1002]— confirm the first new server is healthy. - Migrate every topic onto servers
[0, 1, 2, 1005, 1004]— continue, making suremin.insync.replicasworth of replicas stay on old machines the whole time. If we’d missed something, the old servers were still fully functional for reads and writes. - Migrate every topic onto servers
[0, 1, 2, 3, 4]— no data left on the old servers at all.
Each step took roughly 30 minutes, across around 150 topics and not much data per topic. During each run, I used the Zookeeper CLI (zkCli.sh on the Zookeeper server) to watch the migration directly — the thing to check during replication is the status at get /admin/reassign_partitions, which reports which partitions are still mid-migration for a given topic. Staging and pre-live went without a single hiccup. During the live migration, though, one topic was taking far too long to replicate. Checking the monitoring dashboards, the input/output spikes from data movement had actually finished twenty minutes earlier, but CPU on one of the servers was still high. The logs on that server showed the same message repeating:

Replica(s) 0 pointed at the exact server having replication trouble — the same one with the high CPU. Restarting that Kafka server let the process continue cleanly. If something like this happens to you, it’s also worth checking which server currently holds the controller role, via get /controller in the Zookeeper CLI or the logs — the controller can occasionally hang, and deleting it from Zookeeper with delete /controller forces a new leader election, which can unstick a replication process that’s stuck for that reason.
Summary
Looking back, I’d have liked to plan the whole thing from scratch from day one instead of reaching for fast fixes along the way — but that’s the ideal-world version of this story, and in reality you’re always constrained by time or people. We went through several rounds of problem, then solution, then a new problem, before actually getting a solid grip on our Kafka clusters. You’ll likely see the same pattern if you don’t have an in-house Kafka expert from the start. This approach worked for us, and I hope it gives you a few good ideas for managing your own Kafka clusters, or gets you through a migration with less pain than we had. On a bigger cluster than ours, you’d probably need to think harder about things like data throttling or rack awareness, both mentioned above, and likely a few things we didn’t hit at our scale. Let me know if there’s another part of the setup you’d want to hear about, and I’ll try to cover it.